


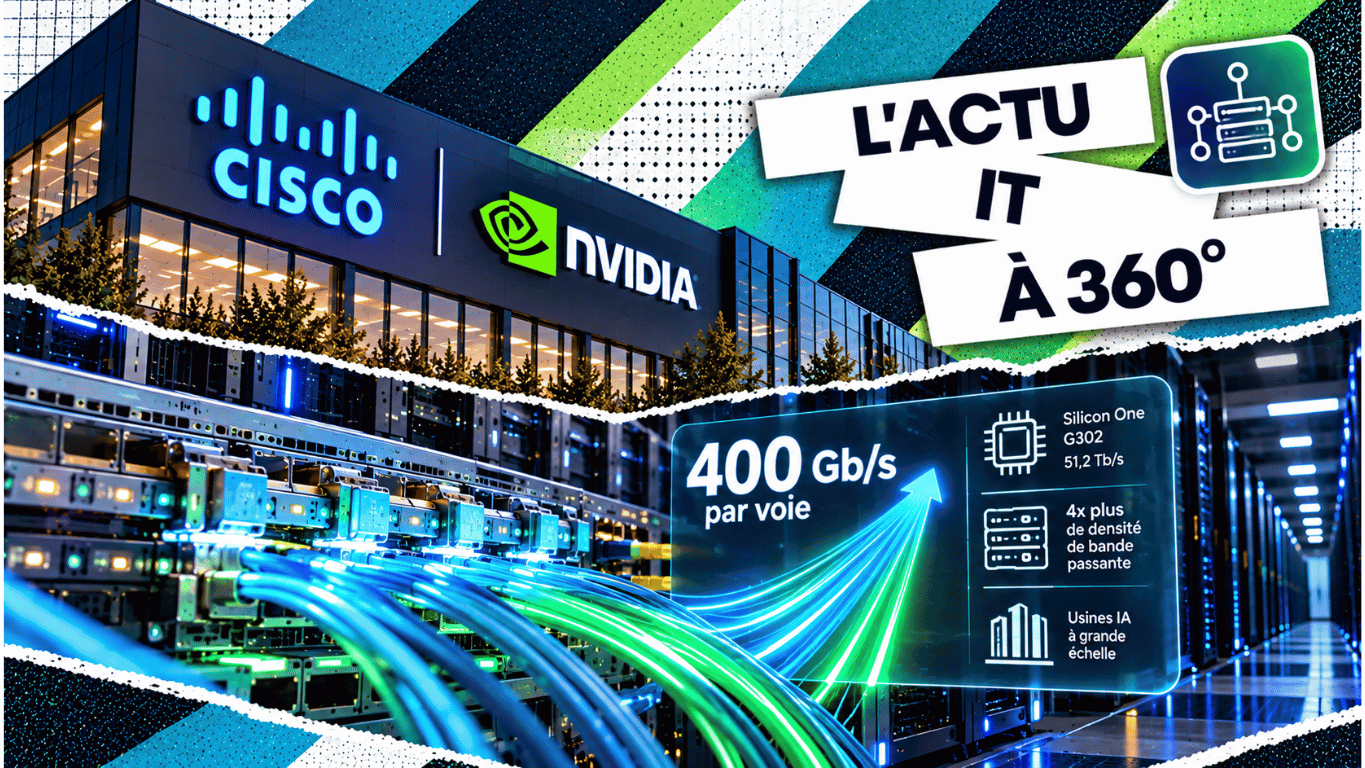
Cisco and NVIDIA have announced a project for a pluggable optical form factor, USFP, capable of supporting 400 Gb/s per lane. Cisco is also unveiling the Silicon One G302 switching chip, rated at 51.2 Tb/s.[1] These announcements address a key challenge for AI infrastructure: accelerators must exchange data quickly enough for the installed computing power to be genuinely usable. They do, however, concern separate components and timelines.
GPUs need to receive and share data
When processing is spread across several accelerators, part of the work depends on exchanges between machines. Waiting for data or for results from another node can slow down the entire computation. Adding GPUs is therefore not always enough to speed up a task if the network or storage is already limiting how fast they are fed.
The difficulty lies in locating the bottleneck. A saturated link, occasional congestion, poor traffic distribution or overly slow storage can all produce similar symptoms. The response must be based on measurements of the workload actually being run, before choosing faster equipment.
G302 powers the rack network while USFP prepares the optics
The G302 is aimed at top-of-rack switches, which connect servers to the data centre network. Cisco is announcing 200 Gb/s SerDes electrical interfaces and expects first shipments before the end of 2026.[1] The 51.2 Tb/s figure refers to aggregate switching capacity, not the throughput of an individual connection.
USFP, developed with NVIDIA, is a proposed optical module form factor. The partners plan an open specification.[1] A distinction must therefore be drawn between the chip being presented and this optical development, rather than attributing already available 400 Gb/s lanes to the G302.
Three figures that describe different things
Throughput is expressed here in bits per second. Aggregate capacity does not correspond to the usable throughput guaranteed to an application.
| Metric | What it describes | What it does not prove |
|---|---|---|
| 51.2 Tb/s | Switching capacity of the G302.[1] | The throughput available to each server. |
| 400 Gb/s per lane | Target per-lane capacity for USFP.[2] | The immediate availability of a complete link. |
| 6.4 Tb/s aggregate | 16 lanes at 400 Gb/s in the USFP project.[2] | An equivalent speed-up of AI applications. |
Density also depends on the number of lanes
The Cisco blog describes 16 lanes at 400 Gb/s, i.e. 6.4 Tb/s aggregate, with a possible evolution to 32 lanes and 12.8 Tb/s. It compares this proposal with 1.6 Tb/s pluggable modules to claim a fourfold increase in bandwidth density.[2] This factor therefore does not stem solely from doubling the per-lane throughput.
Maintenance matters as much as peak throughput
Cisco highlights the retention of field-replaceable modules and established operating practices for pluggable optics.[2] For an operator, the ability to service a module can weigh on the choice of architecture, just as much as throughput or footprint.
Higher density must nonetheless be assessed against cooling, cabling and spare-part availability constraints. The number of interventions, replacement lead times and compatibility conditions can change the real cost of an infrastructure over several years.
Energy gains have yet to be measured on the complete system
Cisco mentions energy efficiency potentially improved by around 1.3 times thanks to 400 Gb/s SerDes.[2] This indication does not mean that a data centre’s total consumption will fall in the same proportion. Higher capacity may also come with an increase in processing volumes.
A meaningful comparison must specify the load, the throughput actually carried and the scope measured. It should include network equipment, optics and cooling. The announcements reviewed do not present an independent benchmark that would allow the gain to be generalised to all environments.
SMEs can draw a sizing method from this
Most SMEs do not need to prepare a network for these speeds right away. However, an organisation that runs several GPU servers or buys remote computing capacity needs to understand what is limiting its workloads. The network is part of the service to be assessed, even when it is managed by a provider.
An illustrative scenario is to compare the same task on one and then several servers, observing duration, GPU utilisation and network traffic. If the time saving remains small, the team also examines storage and how the work is distributed. This test helps establish a diagnosis; it does not prove that the network is necessarily to blame.
The key IT skill: Systems and Network Administration
This development directly calls on Systems and Network Administration. Professionals must understand the paths data takes and distinguish theoretical throughput from observed performance. A capacity stated on a datasheet is not enough to size a service.
Their role includes analysing congestion, latency and dependencies on storage or compute. They must also check interfaces, optical modules and compatible software versions. These checks help avoid an investment that would simply move the bottleneck elsewhere.
Finally, network administration involves monitoring and incident recovery. Metrics must make degradations visible before they have a lasting impact on workloads. Having maintenance access and replacement procedures remains essential, even on a very high-performance infrastructure.
The value of USFP will therefore depend on performance measured on applications, equipment compatibility and operating conditions. To size an infrastructure, the real limits of compute, network and storage must first be identified.
Further reading
Four CCCLX reads on data centres, data and AI infrastructure.
AI powers Nokia: data centres reshape the networking market
Google Cloud Storage Intelligence Advisor detects storage anomalies
Databricks extends Delta Sharing to AI and aims to break down data silos
AI voice agents: Oracle details a LiveKit architecture on OCI
Sources
- 01
Cisco (12 October 2026). “Cisco Advances Scalability and Openness at OCP 2026”. Announcement of the Silicon One G302 switch and the USFP development project with NVIDIA.
- 02
Gartner, B. and Eatherton, W., Cisco Blogs (12 October 2026). “Cisco and NVIDIA Announce USFP: Expanding the Path to AI Connectivity”. Details on lanes, aggregate capacity and the gains announced for the USFP form factor.

AI propels Nokia: data centres are reshaping the networking market
The AI explosion is transforming the infrastructure market Nokia is reaping the full benefits of the rise of artificial intelligence and the proliferation of data centres that comes with it. In the second quarter of 2026, the company’s Network Infrastructure business...

Gemini 3.5 Pro delayed: Google under pressure in the AI race
The race for AI models is speeding up Google is going through a difficult period in the competition over advanced artificial intelligence models. According to several reports in the specialist press, the launch of Gemini 3.5 Pro has reportedly been pushed back by...

Project Glasswing: Anthropic goes on the offensive against software vulnerabilities
A new step for AI applied to cybersecurity Anthropic is pressing ahead with Project Glasswing, an initiative that makes its Claude Mythos Preview model available to specialist cybersecurity players in order to identify and fix vulnerabilities in critical software. The...

Cloud, AI, defence: AWS steps up on every front
AWS makes artificial intelligence a pillar of critical infrastructure At the AWS Summit Washington, D.C. 2026, Amazon Web Services unveiled several developments aimed at government departments, public bodies and critical sectors. The company is strengthening its...

MDASH: the AI helping Microsoft secure Windows
Microsoft hands part of the bug hunt to artificial intelligence Cyberattacks are evolving ever faster, forcing software vendors to detect vulnerabilities before they can even be exploited. To meet this challenge, Microsoft has unveiled MDASH (Microsoft Detection and...

Microsoft speeds up its cybersecurity with AI: defence moves to machine scale
Microsoft wants to regain the upper hand against cyberattacks Cybercriminals are now using artificial intelligence to discover vulnerabilities, automate their attacks and speed up their malicious campaigns. In response, Microsoft is pressing ahead with its Secure...

Free access to Claude Fable 5 extended as Anthropic holds off
A new generation of AI designed for specific uses OpenAI is changing its strategy with the launch of GPT-5.6, a new family of models made up of Sol, Terra and Luna. Rather than offering a single model capable of meeting every need, the company is now betting on a...

OpenAI bets on modular AI with Sol, Terra and Luna
A new generation of AI designed for specific uses OpenAI is changing its strategy with the launch of GPT-5.6, a new family of models made up of Sol, Terra and Luna. Rather than offering a single model capable of meeting every need, the company is now betting on a...

Anthropic’s AI is advancing at a pace that worries cybersecurity specialists
AI models cross a new capability threshold Barely a month after its launch, Claude Mythos Preview is already improving its performance. According to the latest tests published by the UK’s AI Security Institute (AISI), Anthropic’s model now beats its own results from...
Lumo AI 2.0 speeds up without sacrificing data protection
Proton wants to prove that a high-performing AI can also be private The artificial intelligence race is no longer played out solely on model performance. User trust and data protection are now becoming major differentiators. With Lumo AI 2.0, Proton is upgrading its...